Redshift vs Snowflake as a Customer Data Warehouse Destination
Snowflake and Redshift diverge on concurrency, isolation, and tuning.
Redshift and Snowflake look different once the warehouse stops being a tool your analysts query, because now it's a destination your product writes into. An internal analytics decision serves one team, with one workload pattern, under one cloud contract, and you tune it once and leave it alone. A destination decision serves every customer who adopts your product, and each of those customers arrives with a different cloud commitment, a different query pattern, a different compliance obligation, and usage spikes your engineering team does not control and cannot predict. Your product inherits all of it. Concurrency is no longer yours to manage, because customer users drive it. Tenant isolation turns from a best practice into a product safety property, because a failure there exposes one customer's data to another. Cloud lock-in becomes your customer's problem, not an abstraction, because they may already be committed to infrastructure your warehouse choice either respects or fights. Compliance posture decides whether a regulated customer, say in healthcare or government, can use your product. None of this resolves on its own, either: neither Snowflake nor Redshift delivers analytics to an end customer by itself, so both require a separate layer on top. The warehouse choice is the foundation of a stack rather than the whole answer. Get the destination wrong and the damage does not stop at query performance. It becomes a constraint baked into your product's architecture, one that compounds with every new customer you onboard.
How Snowflake and Redshift are architecturally different
These two platforms differ structurally, and that is what decides which one fits a given customer's environment without creating years of engineering debt. Snowflake runs on a three-layer model. Raw data sits in micro-partitions at the storage layer. Compute happens in virtual warehouses, a middle layer where multiple warehouses can query the same underlying data at the same time, so they don't compete for the same compute capacity. A cloud services layer sits on top, handling metadata, authentication, and security. Because storage and compute are separated this way, adding compute capacity never requires touching the data itself, and scaling one does not force you to scale the other.
Redshift works differently. A leader node coordinates incoming queries and distributes the work across compute nodes in a cluster. RA3 instances separate storage from compute at the infrastructure level, but data still has to move from managed storage onto the compute nodes through a local SSD cache, and only then can a query run. That is a meaningfully different mechanism from Snowflake's approach, even though both platforms now talk about storage and compute as "decoupled." Redshift also offers zero-ETL integrations with Aurora, DynamoDB, and SaaS platforms including Salesforce, which removes a pipeline stage entirely for customers who are already running their operations inside AWS.
The administrative burden each platform imposes is the dimension most SaaS product teams underestimate until they are deep into a customer deployment. Snowflake abstracts away physical tuning almost entirely: no indexes to manage, no partitions to define by hand, no vacuum jobs to schedule, because the cloud services layer handles metadata optimization on its own. Redshift asks more of whoever runs it. RA3 instances auto-tune to a degree, but a database administrator still has to watch sort keys, distribution styles, and vacuum processes to keep query speed where it should be. For a SaaS team syncing data into a customer's Redshift cluster, that tuning burden often lands on the customer rather than the vendor, and an under-tuned Redshift cluster turns into a support ticket and, eventually, a churn risk that the product team owns indirectly even though it never touched the configuration.
Concurrency Under Real Customer Load
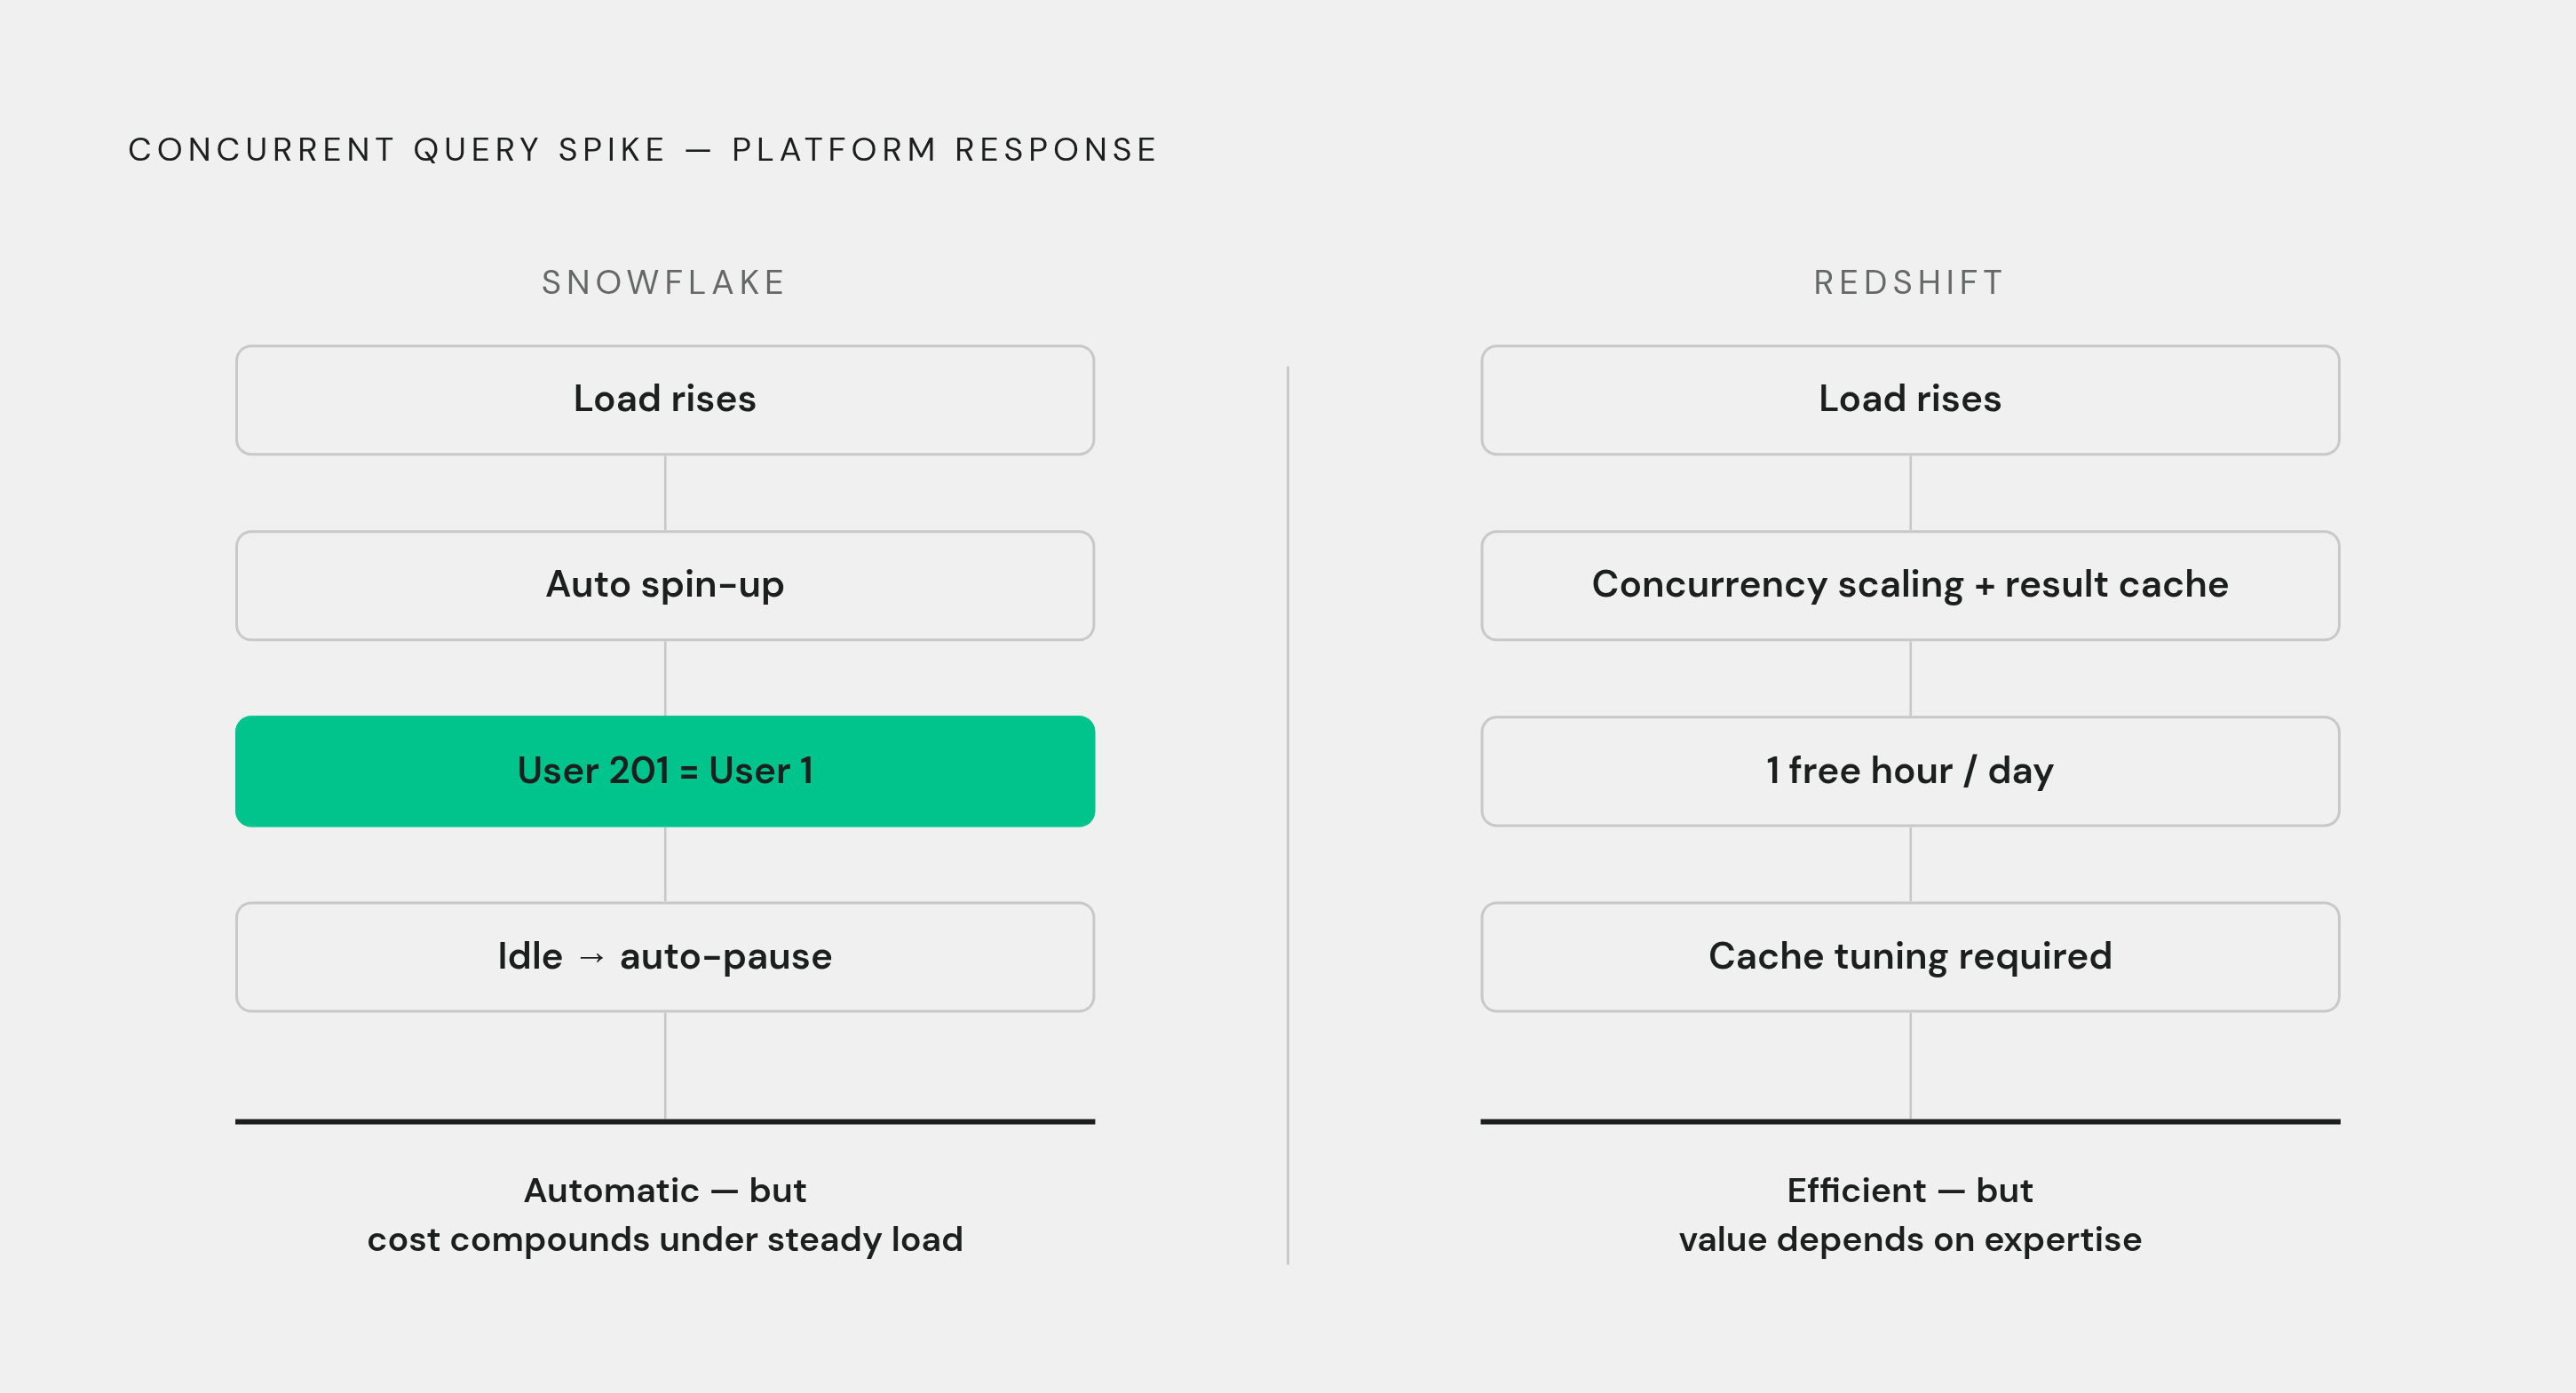
The architectural differences above turn into a concrete latency problem the moment real customers start using the product at the same time. Concurrency is where SaaS teams most often get surprised, because the two platforms answer the same stress test in genuinely different ways, and the wrong choice causes slow dashboards at the exact moment customers are paying the most attention: Monday morning, when every enterprise account logs in at once to check the past week's numbers.
Snowflake handles that spike with multi-cluster warehouses. When concurrent queries increase, Snowflake spins up additional virtual warehouses automatically, so the 201st concurrent user gets roughly the same response time as the first. Idle warehouses pause on their own, so no credits burn when no queries are running. The tradeoff appears in embedded analytics products where dashboards stay active continuously and load keeps growing over time: each additional cluster spins up and burns credits around the clock, and that cost can compound faster than early usage forecasts suggest.
Redshift takes a different approach, combining concurrency scaling with result caching. Customers get up to one free hour of concurrency scaling per day, and RA3 nodes paired with result caching cut cost because they serve repeated tenant queries without spinning up extra compute. AWS extended this capability in May 2026, when zero-ETL ingestion pipelines gained the ability to use concurrency scaling automatically, a change covered further in a June 2026 blog post on multi-warehouse enhancements. That update narrows the gap with Snowflake's multi-cluster model without closing it. The catch with Redshift's approach is that getting real value out of result caching takes specialized data engineering skill that a lot of B2B SaaS teams don't have on staff, and if the customer doesn't have it either, performance can degrade without any clear warning sign.
For product builders, Snowflake's elasticity runs automatically and costs more under steady, constant load, while Redshift's efficiency is real but depends on active tuning to achieve. Which one fits better depends on whether your customers employ the data engineering staff needed to maintain that tuning over time. An embeddable integration layer has to account for this difference before data even reaches the warehouse. Whether the destination can spin up capacity on demand, the way Snowflake does, or depends on result-caching discipline, the way Redshift does, shapes how an ingestion layer should deliver data so it reinforces the platform's strengths instead of creating a bottleneck downstream.
Tenant isolation: how each platform handles the security boundary between your customers' data
Performance problems are visible and recoverable. Isolation failures are neither, which is what makes tenant isolation a different category of risk for SaaS builders than concurrency ever is. Row-level security exists on both Snowflake and Redshift, but neither platform ships a ready-made multi-tenant framework, so what differentiates them is how much custom engineering work each one demands to close that gap. Underestimating that work is how data leakage happens at scale. The question every multi-tenant SaaS product has to answer concretely is this: when Tenant A opens their dashboard, what guarantees that Tenant B's data stays invisible to them, across hundreds or thousands of tenants, no matter how many queries are running at once?
Snowflake answers part of this with row-level security policy objects, which filter query results according to the session context of the user running them, and with object-level access controls that make it more straightforward for developers to build an isolated data model per tenant. Snowflake also supports workload isolation: you can assign separate virtual warehouses per tenant or tenant group, so one tenant running a heavy query does not slow down another tenant's dashboard. None of that comes pre-built, though. Snowflake does not supply a multi-tenant framework out of the box, so the security model still has to be designed and maintained by the product team using it.
Redshift offers row-level security through CREATE RLS POLICY, but putting that in place across hundreds of tenants requires careful design work around IAM roles, database groups, and grants, and tenant-level isolation inside a shared cluster remains custom engineering either way. VPC isolation gives Redshift strong network-level security, but that only protects the perimeter around the cluster. It does not control which rows a given tenant can see inside it. Redshift also has no equivalent to Snowflake's virtual warehouse isolation: tenants share cluster compute unless separate clusters are provisioned for them, and that decision changes the cost model considerably.
The engineering effort required to keep tenant isolation correct grows as the customer base grows, regardless of which platform is in use. Both demand real, ongoing work here. Redshift's cluster-based model adds a layer of cluster-level coordination on top of the row-level policy work that both platforms already require, which makes the total isolation burden on Redshift somewhat heavier in practice.
Cloud commitment and customer warehouse coverage
Cloud coverage decides which customers can even consider each platform before you get to a single technical tradeoff. Snowflake's multi-cloud reach and Redshift's AWS depth each open certain customer segments and close others, so this is partly a market access question, and not just a technical one.
Snowflake runs on AWS, Azure, and Google Cloud, so customers using it avoid being tied to a single cloud vendor. A SaaS product syncing into a customer's Snowflake account does not need to know or care which of the three clouds that customer happens to run on, since the integration works the same way regardless. That multi-cloud posture has not stopped Snowflake from deepening its relationship with AWS specifically: Snowflake signed a $6 billion AWS commitment, a sign of a closer cross-cloud partnership even while Snowflake continues to market itself as cloud-independent.
Redshift, by contrast, runs on AWS only. A customer running on Azure or Google Cloud cannot adopt Redshift without a cloud migration or a hybrid architecture, which is a real barrier for a meaningful share of the enterprise market. For the large segment of buyers who have already standardized on AWS, though, Redshift's native integrations, including S3, Glue, Kinesis, SageMaker, and QuickSight, offer real infrastructure simplicity rather than lock-in cost. Redshift's zero-ETL connections to Aurora, RDS, and DynamoDB let those customers analyze operational data without building a separate pipeline to get it there, and that is a genuine advantage if you're already committed to AWS.
Customers also switch warehouses more often than product teams tend to plan for. One company moved off one warehouse and onto another, and a different company moved off that second warehouse and onto a third. Each case shows that a warehouse decision made today is not necessarily permanent, and a SaaS product that only supports one destination carries real exposure to churn whenever a customer's underlying infrastructure changes. If your SaaS product supports multiple destinations, it absorbs that kind of migration without losing the customer. Once a warehouse is a destination rather than an internal tool, the product itself has to manage these differences: cloud commitments, compliance obligations, and query patterns across many customers. White-label data integration platforms, Prequel among them, handle the ingestion side of that problem, syncing data securely into whichever warehouse the customer has chosen, which frees the product team to focus on the destination architecture decision instead of building and maintaining custom connectors for each one.
The practical rule for SaaS builders follows from where their customers already sit. A customer base concentrated in AWS-native enterprises means Redshift support likely covers most of the addressable market, and the native AWS integrations become a genuine selling point rather than a constraint. If a customer base spreads across cloud providers, including meaningful numbers of Azure and Google Cloud shops, Snowflake's multi-cloud reach covers more ground with a single integration. If you serve both kinds of customers, you need to support both destinations, so the real architectural weight falls on the data connectivity layer above the warehouses, not on the warehouse choice alone.
Compliance posture and cost on each platform
Compliance adds a cost dimension that architecture and cloud coverage do not fully capture on their own. Both platforms carry enterprise-grade certifications, but they price access to the most sensitive compliance features very differently, and that difference changes the total cost of serving customers in healthcare, financial services, or government.
Both platforms offer SOC 2 Type II certification, encryption at rest and in transit, and some form of VPC or private network isolation. Snowflake's certification list goes further: SOC 1 Type II, SOC 2 Type II, ISO 27001, ISO 27017, ISO 27018, and PCI DSS attestation, along with HIPAA-eligible status and, where needed, FedRAMP High and DoD IL5 authorizations. The catch sits in how those features get priced. HIPAA BAA eligibility and customer-managed encryption keys are both gated behind Snowflake's Business Critical edition, a higher-priced tier than the standard offering. Snowflake introduced AI Credit pricing on April 1, 2026, which separates AI feature access from edition tier, but that change left compliance features exactly where they were: locked behind Business Critical regardless of which pricing model a customer uses for AI. Snowflake also offers private network access through AWS PrivateLink, Azure Private Link, and Google Cloud Private Service Connect, keeping traffic inside the cloud provider's own private network, though setting that up takes DNS and routing work on the customer's side, and Snowflake itself cannot run on private cloud or on-premises infrastructure.
Redshift takes a more inclusive approach to pricing these same protections. Granular access management comes through IAM, Lake Formation, cluster encryption, security groups, SSL, and VPC isolation, and those capabilities come included at standard pricing, with no edition upgrade required to get HIPAA-relevant features or encryption. Redshift clusters also run inside a customer's own VPC by default, which gives infrastructure-level isolation as part of the base product rather than as an add-on.
For SaaS builders selling into healthcare or government, that pricing difference changes the total cost of ownership materially: Redshift's compliance features at standard pricing cost less overall than requiring customers to upgrade into Snowflake's Business Critical tier. If you serve multi-cloud enterprises with strict data residency requirements, Snowflake's private connectivity options across all three major clouds can give those customers a path they need, but your product team has to account for the Business Critical tier's cost and the DNS configuration work it requires on the customer's end.
Sources
- Snowflake vs Redshift | Which Data Warehouse Tools Wins In 2026?
- Cloud Data Warehouse Solutions: 6 Platforms Compared 2026
- Snowflake vs. Redshift Comparison: 2026 Deep-Dive
- docs.aws.amazon.com
- aws.amazon.com
- Snowflake vs Redshift: What’s The Difference & How To Choose?
- Security - Encryption, Access Management, Governance - Amazon Redshift
- Implementing multi-tenant patterns in Amazon Redshift using data sharing